
Model Evaluation and Red-Teaming
The standard every Glemad capability must meet before it may advise, before it may act, and for as long as it operates.
Framework record. Version 2.0 · Effective 14 November 2026 · Supersedes version 1.0 (2025) · Owner: Glemad Research, with Security Engineering · Reviewed with the Glemad Safety Framework
Principle
Glemad evaluates decisions, not benchmark scores. The question asked of every capability is whether, under uncertainty and adversarial pressure, inside a live environment, it would take the right action within its authority and leave a record that holds up. A capability that cannot be shown to do this stays in research, whatever it scores elsewhere.
What is evaluated
Five objectives apply to every system:
- Correct interpretation of threats under uncertainty.
- Correct and proportional action.
- Adherence to policy and safety constraints.
- Production of audit-grade evidence.
- Correct prediction of the operational consequence of the system's own action.
They are measured as: containment correctness under constraints, including over-containment; evidence completeness, scored per criterion; cost-weighted false positives, weighted by disruption, human effort and trust eroded; safety counts (policy violations, irreversible actions without approval, blast-radius exceedances), each with a target of zero; and, for predictive systems, state-prediction error at fixed horizons, mission-impact error, counterfactual ranking accuracy, and the correlation between stated uncertainty and realised error.
Capability tiers and the evaluation each triggers
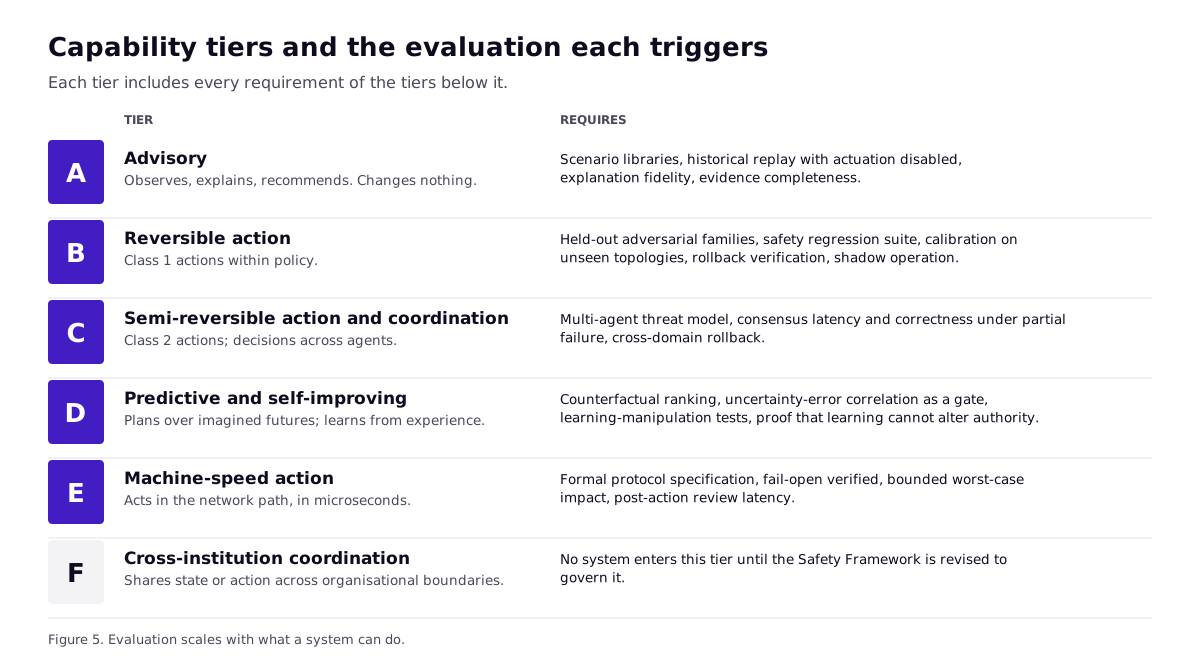
Evaluation scales with what a system can do. Each tier includes every requirement of the tiers below it.
Tier A: Advisory. The system observes, explains and recommends; it changes nothing. Required: scenario-library evaluation, historical replay with actuation disabled, explanation fidelity, evidence completeness.
Tier B: Reversible action. The system may take Class 1 actions within policy. Required: held-out adversarial families, the safety regression suite, calibration on unseen topologies, rollback verification, and shadow operation in a representative environment.
Tier C: Semi-reversible action and multi-agent coordination. The system may take Class 2 actions and reach decisions across agents. Required: the multi-agent threat model (compromised agents, consensus manipulation, partition, telemetry deception), consensus latency and correctness under partial failure, and cross-domain rollback.
Tier D: Predictive and self-improving systems. The system plans over imagined futures or updates its own parameters from experience. Required: counterfactual ranking against matched intervention pairs, uncertainty-error correlation as a gating metric, learning-manipulation tests, change-velocity verification, and proof that learning cannot alter authority or hard rules.
Tier E: Machine-speed action without a person in the loop. The system acts in the network path, in microseconds, under pre-authorised protocols. Required: formal specification of the protocol's trigger and scope, fail-open behaviour verified, bounded worst-case impact demonstrated, and post-action review latency measured.
Tier F: Cross-institution and national-scale coordination. The system shares state or coordinates action across organisational boundaries. Required: privacy and classification controls verified, inter-organisational authority mapping, and evaluation of cascade behaviour across institutions. No Glemad system operates at this tier until the Safety Framework is revised to govern it explicitly.
Release gates
No capability is released, and no deployment is promoted to a higher authority tier, until it has passed the evaluation its tier requires, carries a published scope statement, has run in shadow against the target environment, and has been signed by a Safety Review in which research, engineering, security and policy each participate. A Safety Review may block a release. It cannot be overruled by a commercial decision.
Calibration as a condition of autonomy
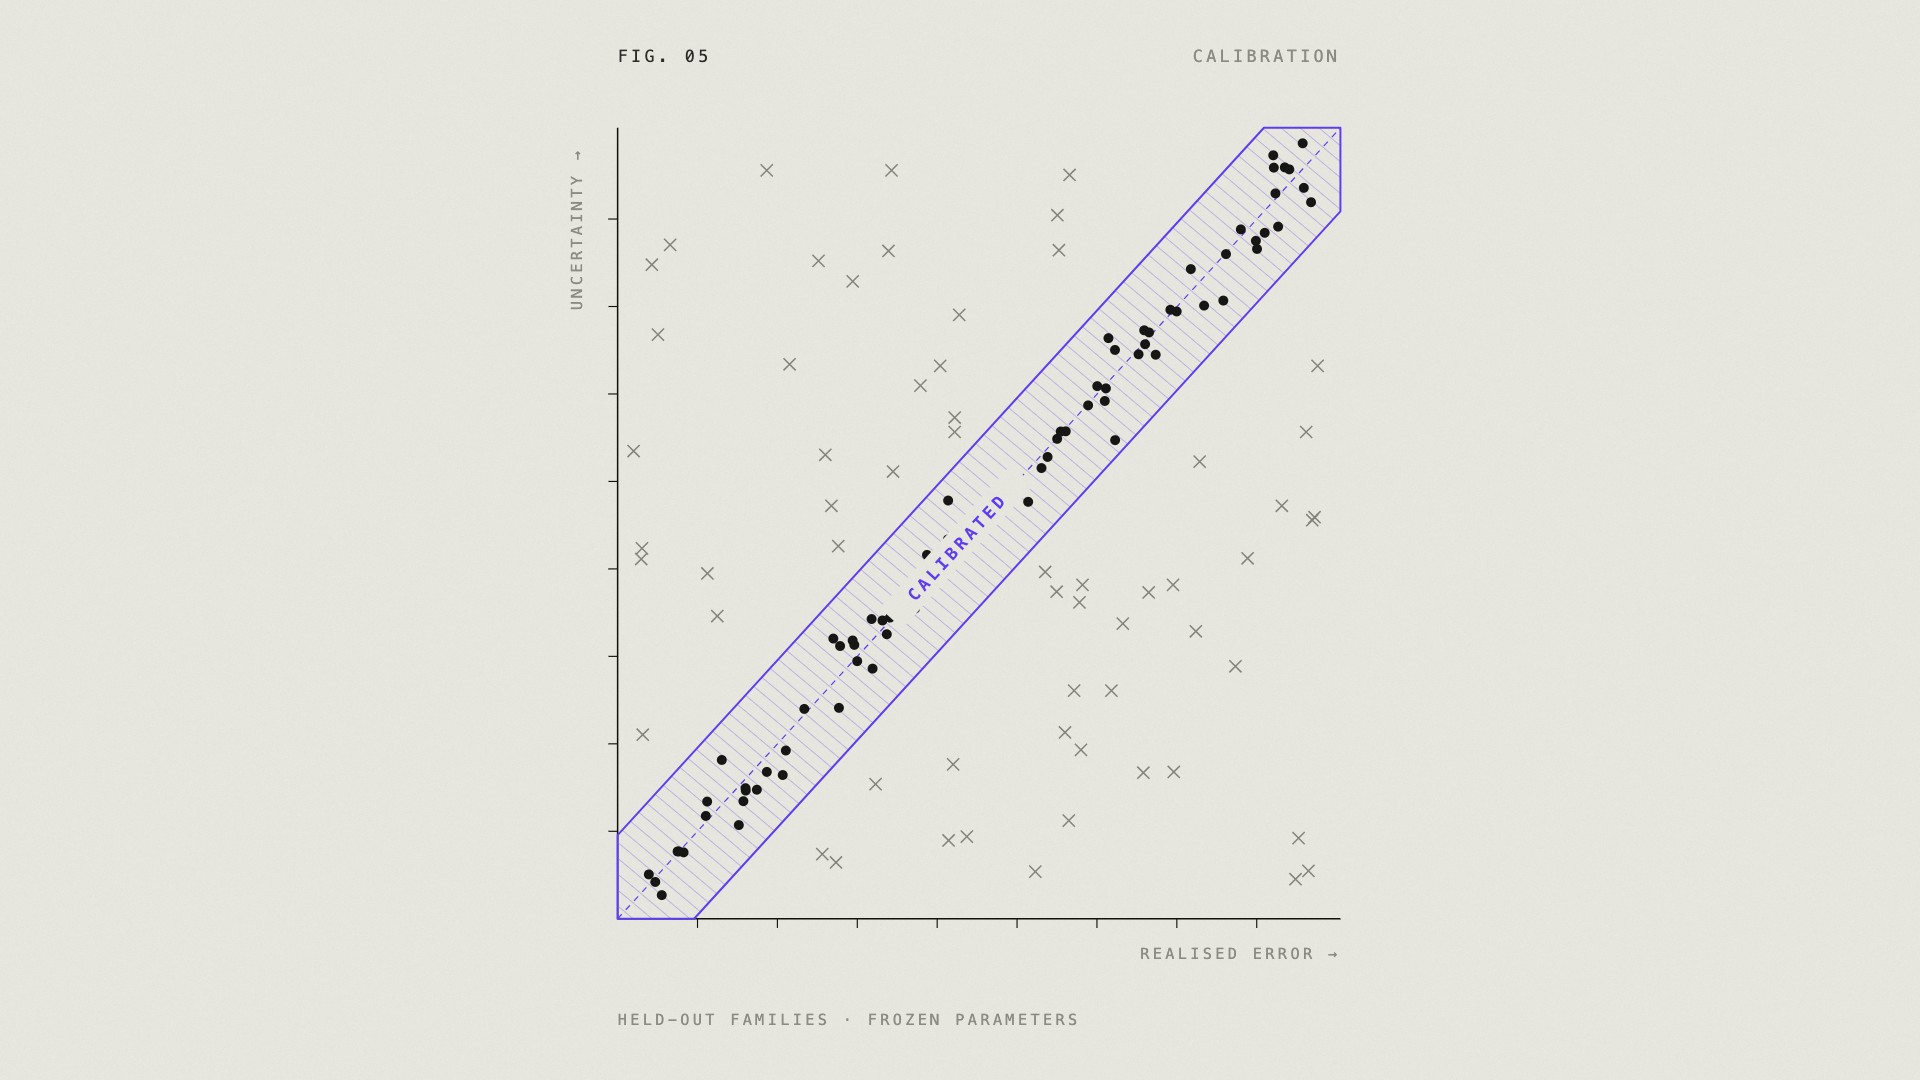
A confidently wrong system is more dangerous than an uncertain one. Glemad measures whether a system's stated uncertainty predicts its actual error, on topologies and strategies it has not seen. If it does not, the system is not granted autonomy, and a deployed system whose calibration fails is returned to advisory operation. This rule has no exception for capability or speed.
Methods
- Historical replay with actuation disabled, proposals compared against documented human response.
- Scenario libraries of incidents, compliance cases and misconfiguration sequences.
- Controlled infrastructure: deployed estates isolated from production, under replayed operational load, attacked with real tooling under written authorisation and stated stopping conditions.
- Matched intervention pairs: alternative defender actions applied from identical snapshots, giving ground truth for what an action causes.
- Safety regression suite: a fixed set including ambiguous identity behaviour, policy exception edges, partial telemetry and conflicting signals, run on every model and policy update.
- Shadow operation in the target environment before any authority is granted.
Rules of evidence
- Final results use frozen scenario families, attacker strategies, topologies, seeds and mission graphs not used for model selection.
- Loss weights and hyperparameters are fixed before final evaluation, on a development split disjoint from the test families.
- Privileged simulator state used in training is never exposed to the system at evaluation.
- Every final run serialises a manifest: code commit, environment and scenario versions, seeds, attacker policy, mission graph version, checkpoints, planner configuration, hardware and timing, stored with raw traces.
- Results are reported with the statistics computed for them.
- Kernel or component timings are never presented as end-to-end response latency.
Red-teaming programme
Glemad red-teams the whole system, the model and everything around it, in three rings.
Internal. Security engineering attacks each release against the published threat model: credentials used through legitimate interfaces, control-plane manipulation, cross-environment traversal, low-signal operation with native tooling, adaptation after containment, AI-optimised attacks; and against the system itself: compromised agents, hypothesis floods, crafted telemetry, policy relaxation, feedback engineered to degrade learning or widen authority, poisoned training data, manipulated observation channels, induced optimism in imagined futures.
Independent. Reviewers outside the team that built the capability, including Glemad research fellows and external specialists under agreement, with access to the threat model and the falsification criteria of every published hypothesis.
Institutional. Institutions that run Glemad systems contribute anonymised scenarios from their own infrastructure context and take part in joint exercises against their deployments.
Findings from any ring are tracked to closure. A finding that reveals a capability acting outside its authority blocks release until resolved.
Reference evaluation
The standard is illustrated by the controlled evaluation reported in Glemad's October 2026 paper on Mission-Causal Adversarial World Models. An isolated cloud estate with gateway, identity, VPN, payment, database, CI/CD, backup, administration, analytics and messaging roles and three mission services was exercised under replayed production load from 18 to 22 August 2026, under written authorisation from the Glemad CISO and stated stopping conditions. Six attack families ran with real tooling; two, adaptive strategy switching and telemetry deception, were held out of training. Model and controller parameters were frozen in advance. Five defender variants completed 1,800 episodes.
The full planner reduced attacker objective success from 4.17 percent to 0.28 percent of episodes and recorded no attacker successes in the 120 held-out episodes. Mission cost was measured alongside security effect throughout, and that measurement shapes the planner's next design.
Evaluation after release
Deployed systems are monitored for drift in reasoning quality, shifts in calibration and deviation from expected behaviour. Regressions trigger refinement, additional training or policy adjustment, each of which passes the safety regression suite and limited deployment before full rollout. Significant events are reviewed with the institution. Learning from review runs under the constraints of the Safe Autonomy Framework.
Publication
Every major release is accompanied by an evaluation report stating methods, results, scope and the manifest fields needed to reconstruct them. Findings that affect a deployed system are communicated to the affected institutions. Research with offensive potential is published with the restraint its potential demands: methods and defensive results in full, operational detail that would materially assist an attacker withheld, and the decision recorded.